Run a Streaming Pipeline (API)
This tutorial covers how to create a streaming instance using the NeuroScale API.
In order to follow along with this tutorial and test out its code on your end, your Python environment should be installed and setup; please look over the Python documentation if this is not the case. Also see NeuroScale Platform and Run a Streaming Pipeline (Dashboard) for information on streaming instances.
Creating a streaming instance requires the pipeline ID, parameters and properly formatted metadata, which can be extracted from Dashboard or using the NeuroScale API. This tutorial covers both methods.
1. Extracting Pipeline Info from Dashboard
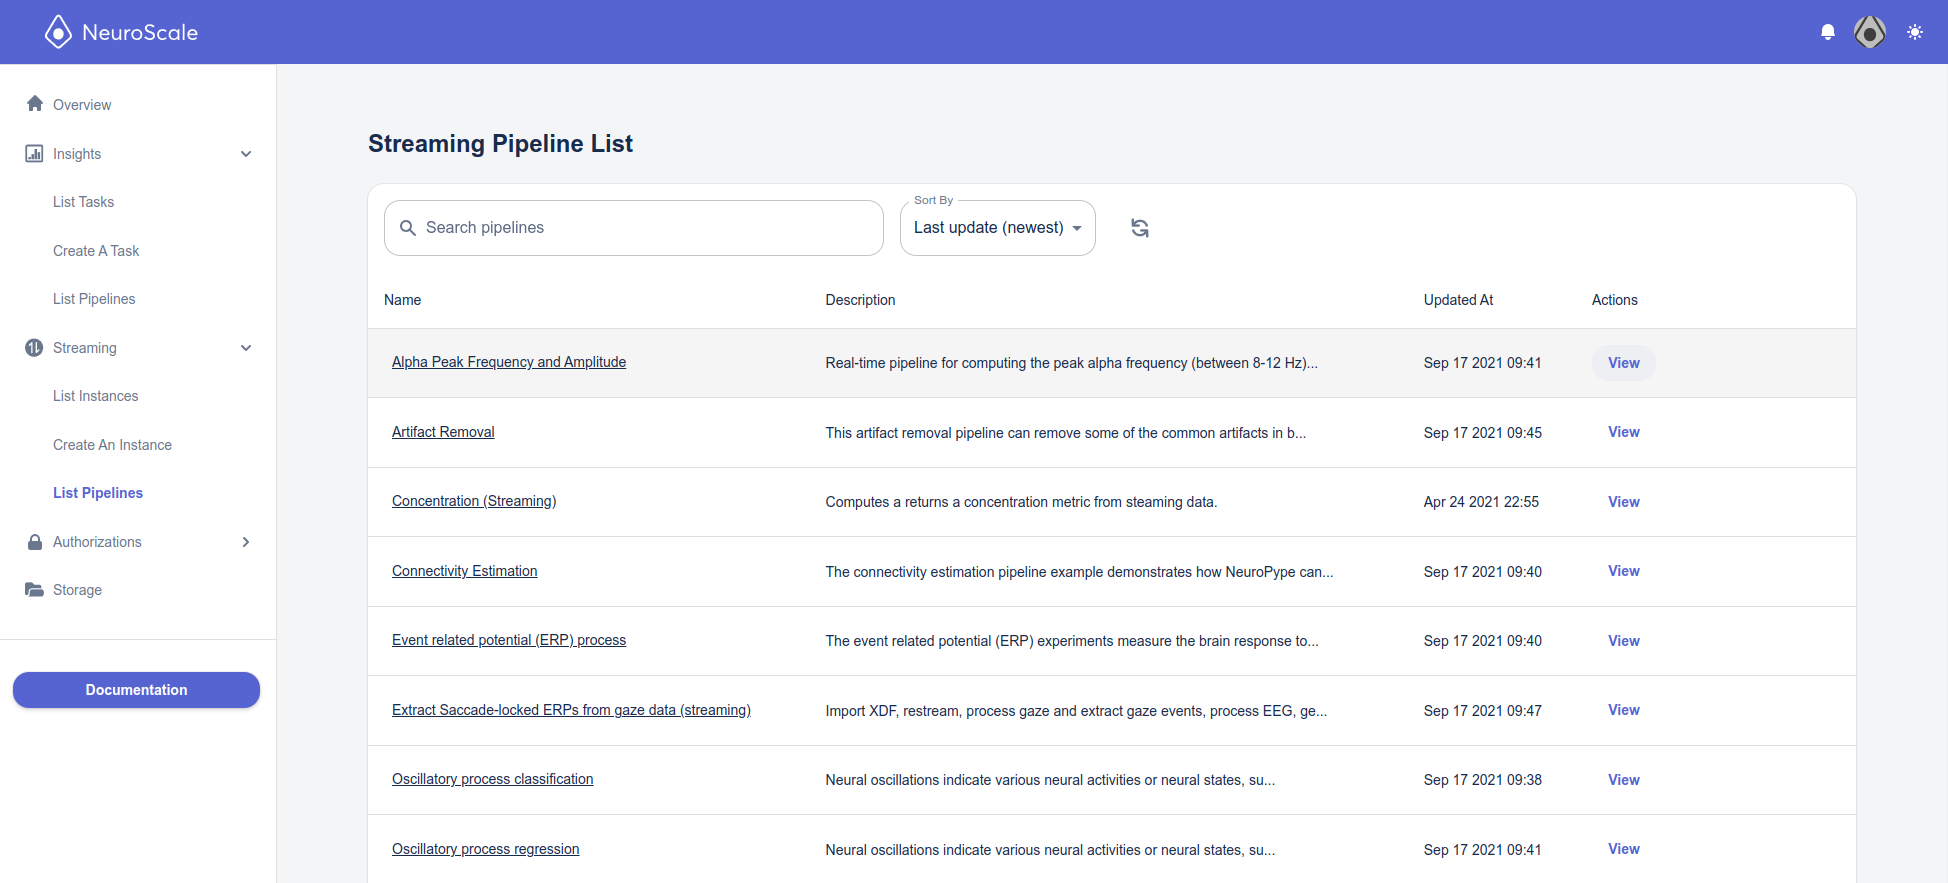
First we must navigate to the List of Available Pipelines page and View the pipeline of interest, shown below in Figure 1. Note that the Pipeline must be of type Stream; Run a Batch Task (API) covers how how to create Pipelines of type Batch.
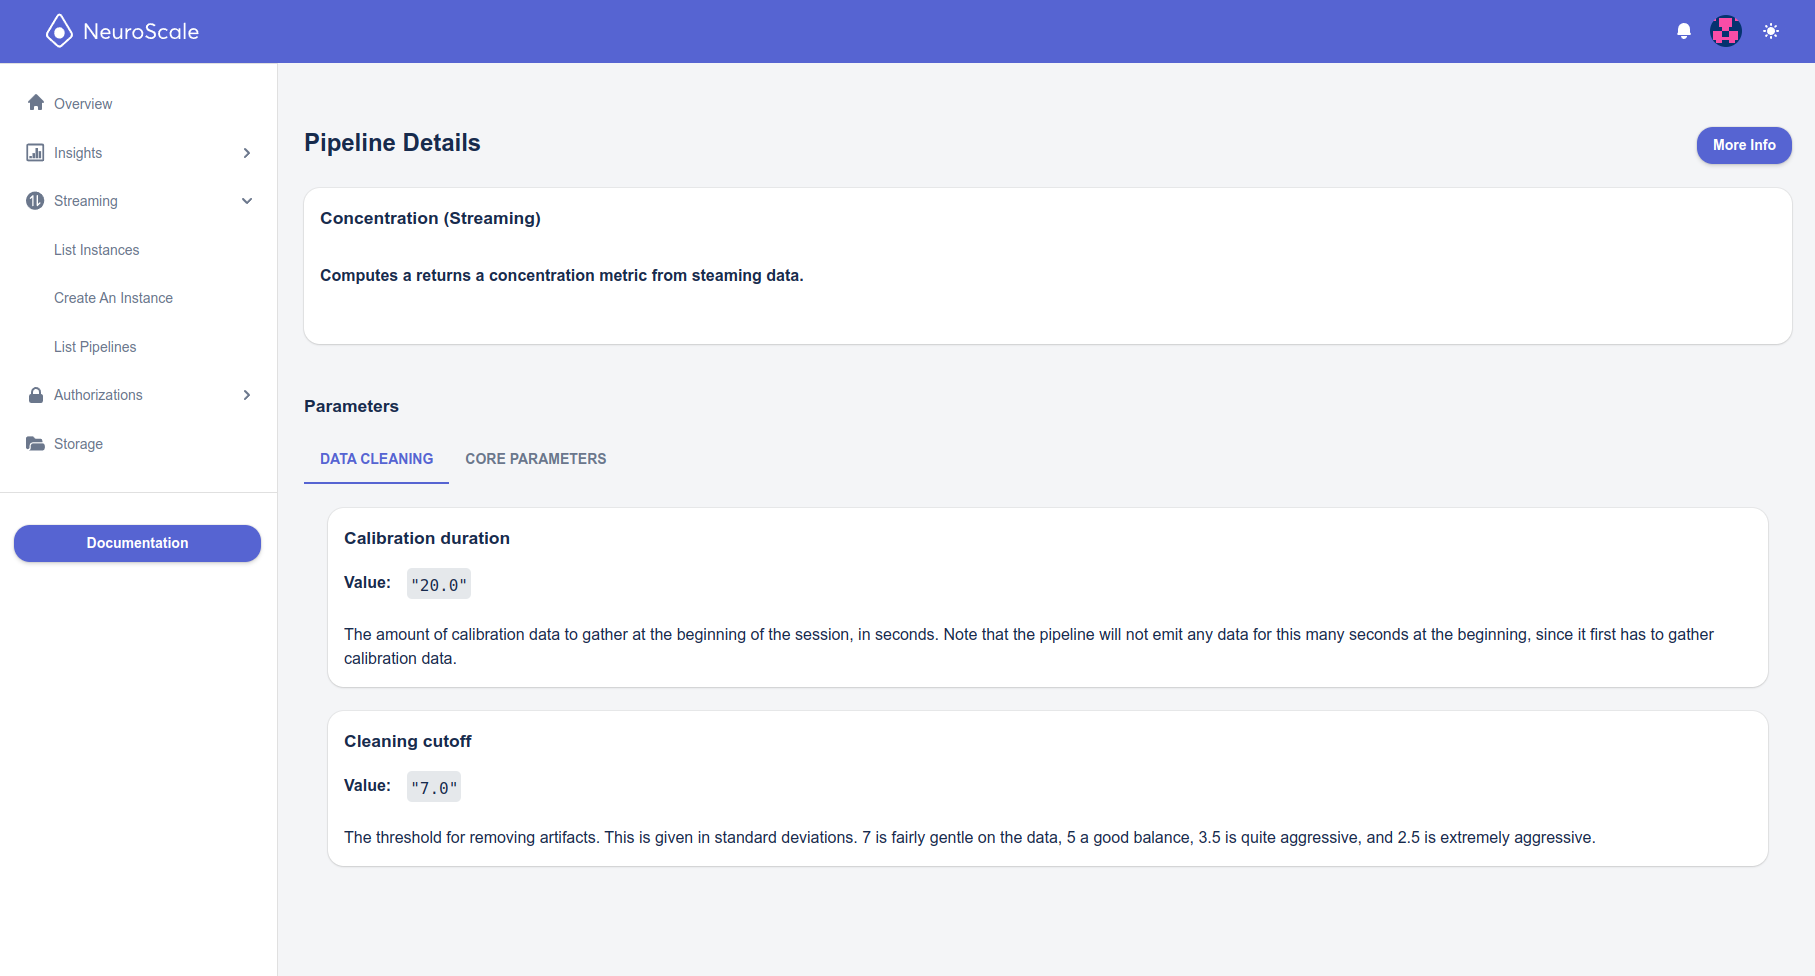
This brings us to the View an Existing Pipeline page, which displays the pipeline ID, name, description, parameters, and metadata etc.
The pipeline metadata, which includes defining the pipelines in and out streams and channels, is available in the "More Info" button:
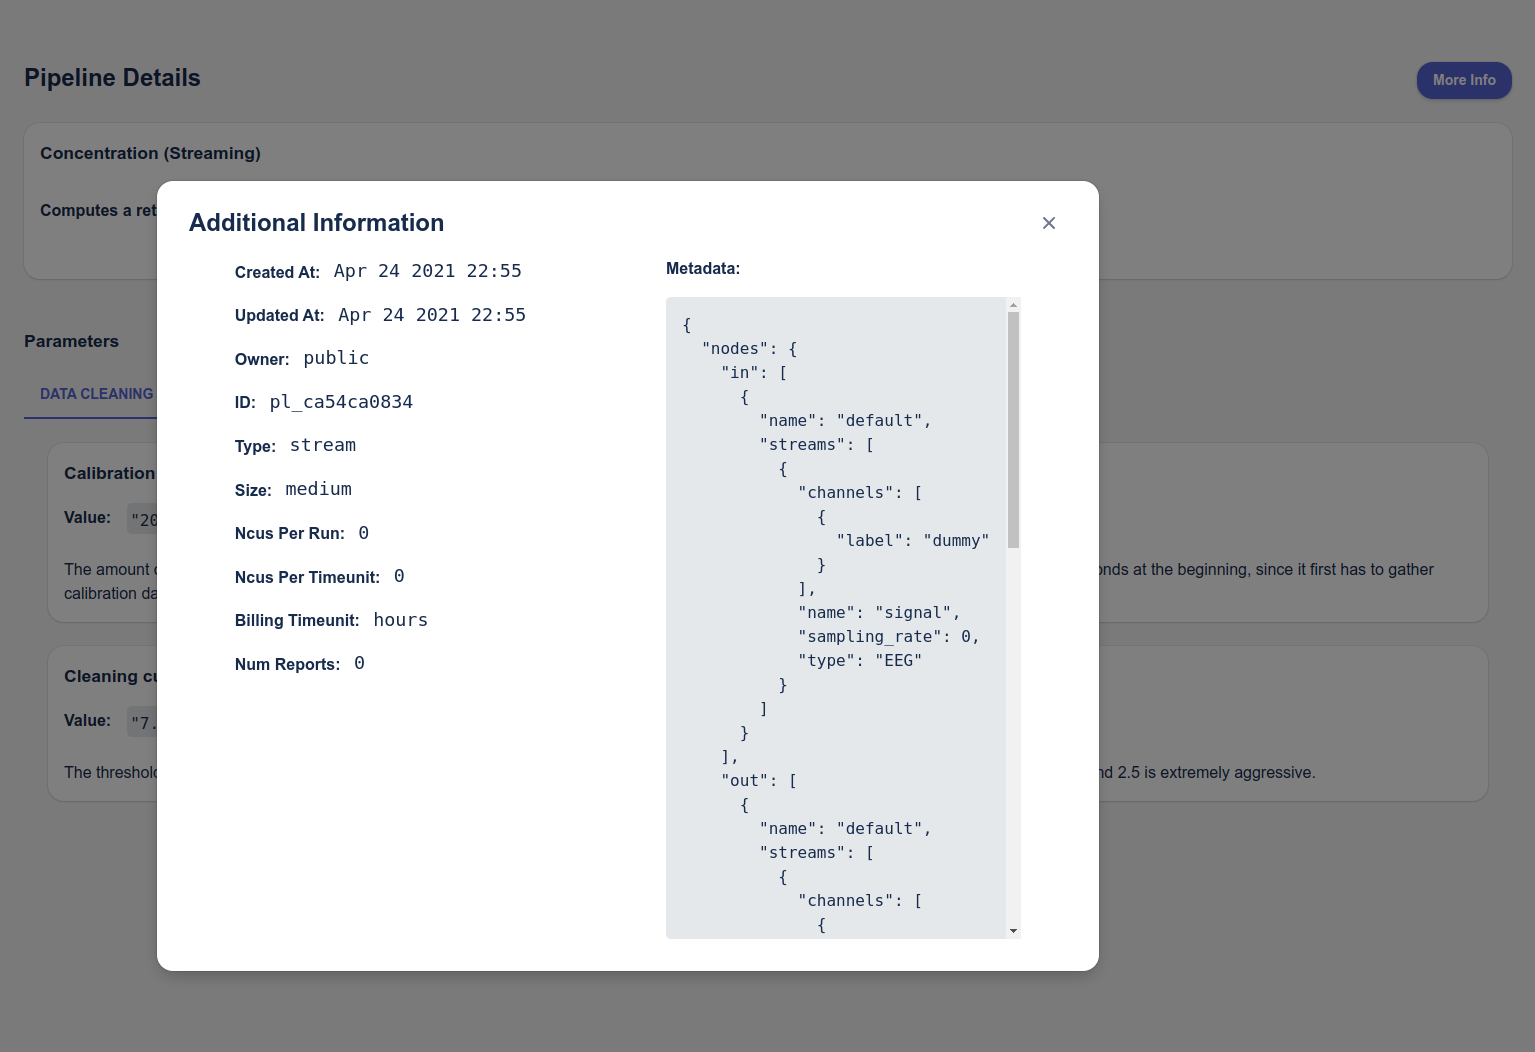
We can extract the pipeline ID, parameters and metadata by copying the information and pasting into some python code (more details in the Assemble Pipeline Info and Launch section).
Some pipelines may not have any exposed parameters. The number of pipeline parameters will depend on the how many parameters were exposed to the user when the pipeline was designed, some pipelines may have more parameters that are user configurable. These parameters expose specifications that govern pipeline behavior and allow the user to adjust their pipeline with each run.
If you're creating your own pipelines with Neuropype and uploading them to Neuroscale, you can choose which parameters you want to expose at runtime by using the ParameterPort node.
2. Extracting Pipeline Info with the API
Prerequisite Information
Lets start our code with some prerequisite user information:
import requests

# we need to define the Neuroscale API URL to use
api_url = 'https://api.neuroscale.io'

# you also need to provide your own access token; for security
# reasons it is best to keep this string out of your code commits and instead
# read it from an environment variable or file (if you do not have a token,
# check our online documentation on how to generate one from your
# username/password combination)
access_token = '<your-access-token>'

# construct the HTTP header that will be used for authorization
auth_header = {'Authorization': 'Bearer ' + access_token}

# next we need to identify the pipeline that we want to launch on Neuroscale
# in this example we will launch the "Echo" pipeline; that pipeline will parse
# your data but send it back unchanged for testing
pipeline_name = 'Echo'
The access_token will be set to one of the authorization tokens for your account. (See Create Access Tokens for more info on access tokens.) The auth_header creates the HTTP header using the access_token. The api_url should be set the NeuroScale API URL shown in the above code snippet (unless instructed otherwise under special circumstances). The pipeline_name is the name of the pipeline we want run.
Find Pipeline and Extract Information
This prerequisite information will be used to find the pipeline of interest and extract the pipeline details:
# init pipeline details
pipeline_id = None
pipeline_parameters = None
pipeline_metadata = None

# next we will look up the pipeline of interest by name from the list
# of available pipelines
r = requests.get(api_url + '/v1/pipelines', headers=auth_header)
if r.status_code == 200:  # 200: ok
    body = r.json()
    pipelines = body['data']
    # now go through all pipelines and pick the one that has a matching name
    for p in pipelines:
        if p['name'] == pipeline_name:
            pipeline_id = p['id']
            pipeline_parameters = p['parameters']
            pipeline_metadata = p['metadata']
            break
    else:
        print("ERROR: Could not find a pipeline named '%s'" % pipeline_name)
        exit(1)
else:
    print("ERROR: Could not query available pipelines (HTTP %s); check "
          "your API URL and credentials." % r.status_code)

if pipeline_id is not None and pipeline_metadata is not None and pipeline_parameters is not None:
    print("pipeline_id = %s" % pipeline_id)
    print("pipeline_parameters = %s" % pipeline_parameters)
    print("pipeline_metadata = %s" % pipeline_metadata)
Here all available pipelines are found with the requests.get REST command, the pipeline of interest is matched by name, and the pipeline of interest's ID, parameters and metadataare extracted.
Configure Pipeline Parameters
Both Dashboard and NeuroScale API pipeline information extraction methods result in the following pipeline information:
pipeline_id = pl_LnPnnWWR85mz6soS5SZCme
pipeline_parameters = {}
pipeline_metadata = {'nodes': {'out': [{'streams': [{'type': 'Custom', 'channels': [{'label': 'msg'}], 'sampling_rate': 0, 'name': 'echo'}], 'name': 'default'}], 'in': [{'streams': [{'type': 'Custom', 'channels': [{'label': 'msg'}], 'sampling_rate': 0, 'name': 'echo'}], 'name': 'default'}]}}
The Echo pipeline does not have any exposed pipeline parameters, meaning the pipeline's parameters are fixed to the initial design and its behavior cannot be adjusted by the user on each run. Lets take a look at the Simple Bandpower pipeline's information, which has an exposed parameter:
pipeline_id = pl_LuDcaNQm6eAfnHabnKZGKJ
pipeline_parameters = {'win_len': {'value': '1', 'type': 'string', 'verbose_name': None, 'expert': False, 'is_filename': False, 'category': '', 'description': 'Length of Moving Average window in seconds'}}
pipeline_metadata = {'nodes': {'out': [{'streams': [{'channels': [{'label': 'dummy'}], 'type': 'Control', 'name': 'signal', 'sampling_rate': 10.0}], 'name': 'default'}], 'in': [{'streams': [{'channels': [{'label': 'dummy'}], 'type': 'EEG', 'name': 'signal', 'sampling_rate': 0.0}], 'name': 'default'}]}}
Here you can see Simple Bandpower's pipeline parameter win_len, (Length of Moving Average window in seconds) and its accompanying details are accessible, which means you can adjust its value to your liking before each launch. For example, if you want a longer moving average window you can set the win_len value to 60 seconds:
pipeline_parameters = {'win_len': {'value': '60', 'type': 'string', 'verbose_name': None, 'expert': False, 'is_filename': False, 'category': '', 'description': 'Length of Moving Average window in seconds'}}
Update Parameters of a Running Pipeline
It's possible to change the parameters of a pipeline while it's running, using the NeuroScale API, and see the results in real-time. See the Modify Parameters in Real-Time for details.
Assemble Pipeline Information and Launch
Now our pipeline information configured lets assemble our pipeline information and launch our streaming instance using a requests.post REST command, as shown below. This command returns the ID of the instance in the response body, which you should save so that you can use it to terminate the instance later.
# assemble the final launch options for the pipeline
params = {"pipeline": pipeline_id,
          "metadata": pipeline_metadata,
          "parameters":  pipeline_parameters,
          "encoding": 'msgpack'}
# to launch our processing pipeline now we need to create a new "instance"
# of the desired pipeline (a running piece of code)
# IMPORTANT: note that, once the instance has been created, you are
# consuming resources in the cloud until you destroy the instance again
r = requests.post(api_url + '/v1/instances', headers=auth_header, json=params)
if r.status_code == 201 or r.status_code == 200:  # 201: created / 200: ok
    # we need to extract the instance id from the response so we can shut it
    # down again later (note: it's instructive to print out the JSON response)
    body = r.json()
    instance_id = body['id']
else:
    print("ERROR: Could not post (HTTP %s); check "
          "your API URL and credentials." % r.status_code)
If you have not received a status code error your streaming instance is now launched and will be ready to receive and return data shortly!
Check the Streaming Instance's State
Now that your streaming instance is launched you can check its current state, which can be in any of the following states: configuring, running, error or terminated. If you see an error status your streaming instance setup failed, please check the Troubleshooting your Pipeline Configuration section in the Troubleshooting page for common mistakes that cause this error.
# check instance's current state
instance_state = None
if instance_id is not None:
    r = requests.get(api_url + '/v1/instances/' + instance_id, headers=auth_header, json=params)
    if r.status_code == 201 or r.status_code == 200:  # 201: created / 200: ok
        body = r.json()
        instance_state = body['state']
        print("Streaming Instance '%s' current state: '%s'" % (instance_id, instance_state))
    else:
        print("ERROR: Could not get (HTTP %s); check "
              "your API URL and credentials." % r.status_code)
Clean Up
Once you've finished using your streaming instance, delete it using a requests.delete command and passing the instance_id that was saved earlier.
# do not forget to terminate the instance after you are done using it
r = requests.delete(api_url + '/v1/instances/' + instance_id,
                    headers={'Authorization': 'Bearer ' + access_token})
if r.status_code == 204:
    print('instance %s was deleted successfully' % instance_id)
else:
    print('ERROR: instance %s was not deleted (HTTP %i)' % (instance_id, r.status_code))